posted in Technology

Sam Altman says OpenAI will not go public this year as AI fears grow
Archive link: archive.ph/U1zEK
www.sfchronicle.com/tech/article/openai-ipo-delay-altman-22430043.phpposted in Technology
Sam Altman says OpenAI will not go public this year as AI fears grow
Archive link: archive.ph/U1zEK
www.sfchronicle.com/tech/article/openai-ipo-delay-altman-22430043.phpReplying to @fubarx@lemmy.world
I don’t see how they’re going to meet their revenue projections when open models are largely turning LLMs into a free commodity. So far in 2026, we’ve gone from local LLMs being a toy to Qwen 3.8 27B giving the latest Sonnet 5 a run for its money. The OpenCode desktop app is also almost at parity with the Claude desktop app as well and I’ve heard Pi is pretty good too.
Now we are seeing techniques like a “phrase book” evolving to allowing a large portion of a huge model to reside on a SSD instead of in RAM / VRAM so that Opus-class models can run on a gaming PC. For example, this video is nuts: m.youtube.com/watch?v=IH8XmxiwliQ
OpenAI and Anthropic know they’re cooked, so that’s why they’re talking all this nonsense trying to keep the shell game going a while longer. 🍿
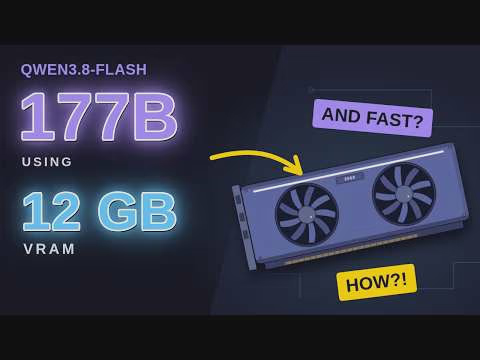 YouTubeIs Frontier Class Local AI Finally Practical?
Replying to @melfie@lemmy.zip
I’m so glad an at home competitive solution to the AI fuckery is here now. I hope this fast forwards the bubble bursting and pc prices go back down when an iPhone or Android phone can run an equally good AI on the device itself.
Replying to @PalmTreeIsBestTree@lemmy.world
Maybe not a mobile device, but running decent local models is definitely within reach for the average consumer today by simply adding a GPU with lots of VRAM to their existing PC.
Replying to @isVeryLoud@lemmy.ca
I mean yes but those gpus are not necessarily within reach of the average consumer anymore. Even if you got one for a grand which is a lot of money you would have cooling and enclosure costs, possibly additional hardware.
Replying to @Squizzy@lemmy.world
Nah I got an RX 6800 XT for $300 with 16 GB VRAM, perfectly cromulent for a 27B model.
Replying to @isVeryLoud@lemmy.ca
Thats is pretty decent alright, I had heard 24 was what was needed for decent local AI.
Replying to @Squizzy@lemmy.world
24 is ideal, 16 works fine especially with some MoE offloading. If you use llama-swap, a fast PCIe bus and fast storage is ideal. Takes about 20 seconds to swap between two models on my X570 board.