posted in Selfhosted

How do you monitor your servers?
Running services, network usage, memory usage, bandwidth, disk I/O, successful logins, whether the thing is even alive, etc…
So far my only method has been “hope and pray”.
posted in Selfhosted
How do you monitor your servers?
Running services, network usage, memory usage, bandwidth, disk I/O, successful logins, whether the thing is even alive, etc…
So far my only method has been “hope and pray”.
Replying to @user224@lemmy.sdf.org
Cockpit. Total gamechanger for me. I don’t have to ssh to my boxes individually to see what’s going on. Instead it’s a web UI AND you can connect basically every server you want to one instance.
github.com/cockpit-project/cockpit
That said. For individual servers?
htop/nmon (Get nmon straight from the source! nmon.sourceforge.io/pmwiki.php) for a birds-eye sysmon view of things
ps -ef | grep <whatever you’re looking for> for investigating stuck/hung/zombie processes
dmseg
tail -f /var/log (or whatever log file you care about)
netstat for net statistics (i think ntop used to be a thing but idk anymore>…)
df -h to look at disk usage
those are all that come to mind right away.
EDIT: formatting and quick explanation of what each tool does
 GitHubGitHub - cockpit-project/cockpit: Cockpit is a web-based graphical interface for servers.Cockpit is a web-based graphical interface for servers. - cockpit-project/cockpit

Lol I go to all of my server’s specific cockpit addresses, sounds like I’m doing it wrong, I’ll need to look at connecting them
Replying to @Owljfien@piefed.world
So it turns out… you can’t connect them anymore… The feature is deprecated
docs.cockpit-project.org/…/feature-machines.html
(also, I wanted to just link my response from another user who had asimilar question but for whateVER reasyon, Alx won’t let me??)
Replying to @happy_wheels@lemmy.blahaj.zone
It’s amazing the risk profile of that.
Replying to @happy_wheels@lemmy.blahaj.zone
How do you configure adding multiple servers to the same instance?
Replying to @nosuchanon@lemmy.world
So I actually just went to make a guide on this, demonstrating on my ubuntu 26.04 lab vps, and it appears the connect option is not there.
However on my 24.04 lab vps, it’s there. Same with my local 22.04 systems (yes I know I have to upgrade lmao)
I went to cockpit docks and sure enough, the feature is deprecated :( Dang.
docs.cockpit-project.org/…/feature-machines.html
It was really cool though while it worked.
Replying to @user224@lemmy.sdf.org
I have a robust monitoring system for my Jellyfin server, been running for the last few years. Checks in periodically, at least once per 24 hours and notifies me if it’s down. Doesn’t use any electricity, but does consume a good amount of Cheerios and mac & cheese.
Replying to @owenfromcanada@lemmy.ca
Does this monitoring system also happen to be a dependent on your taxes?
Replying to @scottmeme@sh.itjust.works
I’ve got a few of those services running.
Replying to @owenfromcanada@lemmy.ca
Lies! It uses electricity!
Replying to @ten8tp@reddthat.com
Indirectly. But as another commenter pointed out, it balances out with the tax rebates.
Replying to @user224@lemmy.sdf.org
Uptime Kuma, only really care if it’s up or not. Got about 30 services monitored, sending notifications to Signal.
Replying to @user224@lemmy.sdf.org
I use naemon (nagios fork) and grafana Loki Prometheus influxdb
Replying to @user224@lemmy.sdf.org
I pay a group of schoolchildren to refresh a group of browser tabs and yell if anything isn’t responding.
There are plenty of previous threads with recent answers if you search.
Replying to @user224@lemmy.sdf.org
Uptime Kuma! For HDDs I have them report their “ping” as percentage full
Replying to @lIlIlIlIlIlIl@lemmy.world
Can you teach me this wizardry?
Replying to @WeirdGoesPro@lemmy.dbzer0.com
Sure! In Uptime Kuma, add a monitor with type Push. It gives you a URL with a unique token, and the monitor goes into “down” state if nothing calls that URL within the heartbeat interval. Then have a cron (or a systemd timer or whatever) run this on the machine with the drive every 5 or 10 minutes:
use=$(df --output=pcent /mnt/yourdrive | tail -1 | tr -dc ‘0-9’)
curl -fsS -G “http://your-kuma:3001/api/push/TOKEN --data-urlencode “status=up” --data-urlencode “msg=${use}% used” --data-urlencode “ping=${use}”
Ping is of course meant to be response time, but Kuma will graph any number you toss in, so you get a “filled” chart for the drive. I also send status=down once usage passes a threshold. And if the box itself should fall over for some reason, the missing check-ins trigger the alert too.
(I typed this quick on my phone, so please double-check and probably don’t blindly copy-paste)
Replying to @lIlIlIlIlIlIl@lemmy.world
Thank you! This is dope!
Lights are on, server is on.
Replying to @Carrots@quokk.au
I recently found out that this is not always true.
I never said anything about it responding.
Replying to @Carrots@quokk.au
Kernel panic?
My kernel is chill.
Replying to @user224@lemmy.sdf.org
Whining from end users.
Replying to @user224@lemmy.sdf.org
I started with uptime kuma since it was simple and light on resources. I’ve switched to checkmk community (formerly raw) and really enjoying it. It’s telling me so many things that are wrong that I missed. Like that one time I made a snapshot of a VM then forgot about it for 113 days…
Replying to @Limeade3425@lemmy.zip
@Limeade3425 @user224 how did you discover that with checkmk?
Replying to @apex@mastodon.uno
With Uptime Kuma, I just used ping and http sensors so that I knew my stuff was up. When I switched to CheckMK, I installed the agent on all servers and that brought quite a bit more info in, then I added the Proxmox integration and that gave me the snapshot info (as well as more info). I think it automatically pulled in my ZFS info, like zpool status. Then added smart monitoring to my storage so that I can see that my hard drives have been spinning for 13 years and 266 days 😅
Replying to @user224@lemmy.sdf.org
I get a text pretty quickly.
Replying to @user224@lemmy.sdf.org
I sync my podcasts hourly with Nextcloud and poddersync, so when my servers go down, my phone beeps at me.
Replying to @user224@lemmy.sdf.org
I use Alloy to collect Metrics of the host (Disk usage, CPU, Ram, etc.) and different logs. With Grafana the data is then displayed as a daschboard. If everything goes south, Alertmanager sends Mails to me
Replying to @user224@lemmy.sdf.org
I usually just walk down the hall and move the mouse. I don’t really need remote monitoring. 😅
Replying to @user224@lemmy.sdf.org
I use nagios
That’s the neat part, I don’t.
Prometheus + grafana. It’s overkill tbh, most of the services restart automatically and I mostly ignore it. (it’s an artifact from life where I cared about it)
Replying to @esc@piefed.social
Exactly this scenario at my place as well. 😄
Replying to @user224@lemmy.sdf.org
Zabbix
Replying to @user224@lemmy.sdf.org
SNMP.
The old engine was nagios. The new engine will be telegraf -> mqtt -> brokerfest -> timescale -> Prometheus.
I guess. Not sure yet. The brokerfest is a series of broker pubsub between sites to both split out data from the stream for off-site CC, or pull its own subscriptions in. Data could go host <- telegraf -> broker -> remote broker -> remote timescale -> remote Prometheus
Replying to @user224@lemmy.sdf.org
I vibe coded a monitor that shows me all the logs and other stuff. And im using netbird cloud (free version) to setup dns so all my services have url “servicexyz.home.internal”.
So i just connect to netbird vpn on my phone and go to that url.
You can pretty much use any of the other tools mentioned in this thread with this kind of setup, heck you can write a simple fastapi server that just runs “top” and return it (it would be like 20-30 lines of python) over a url that you can from anywhere as long as you are connected to your vpn
Replying to @user224@lemmy.sdf.org
A script checks container status and accessibility, and pushes a ntfy alert if it goes down. Healthchecks.io reports if the whole Pi goes down.
When logged in locally, I use btop to see an overview of what’s happening.
Other than that, I have relevant Prometheus exporters in every machine (node exporter in all machines, specific exporters by the workload), hooked up over Wireguard to my monitoring solution offsite.
The phone I actually carry around has a ntfy client talking to ntfy server on the aforementioned monitoring solution, so I get buzzes when something goes down.
Btw, does anybody happen to know where I could get a comprehensive
Replying to @user224@lemmy.sdf.org
I use FreeBSD so I don’t need to check it to make sure it’s working properly
Wasn’t there an RCE recently discovered with AI?
Replying to @moldy_rice@piefed.keyboardvagabond.com
You’d need to be running kerberised NFS in the kernel, give the attacker access to your NFS server, and have a valid kerberos login
I don’t know anyone sharing NFS access let alone opening it up on the open internet
Cockpit on each server (microos) and bezel for a lite centralized monitoring/alert stack. I have a bespoke gitops on each server running ansible hourly, and ntfy pings for failure on these. Also healthchecks.Io for heartbeat/backups, other critical infra checks
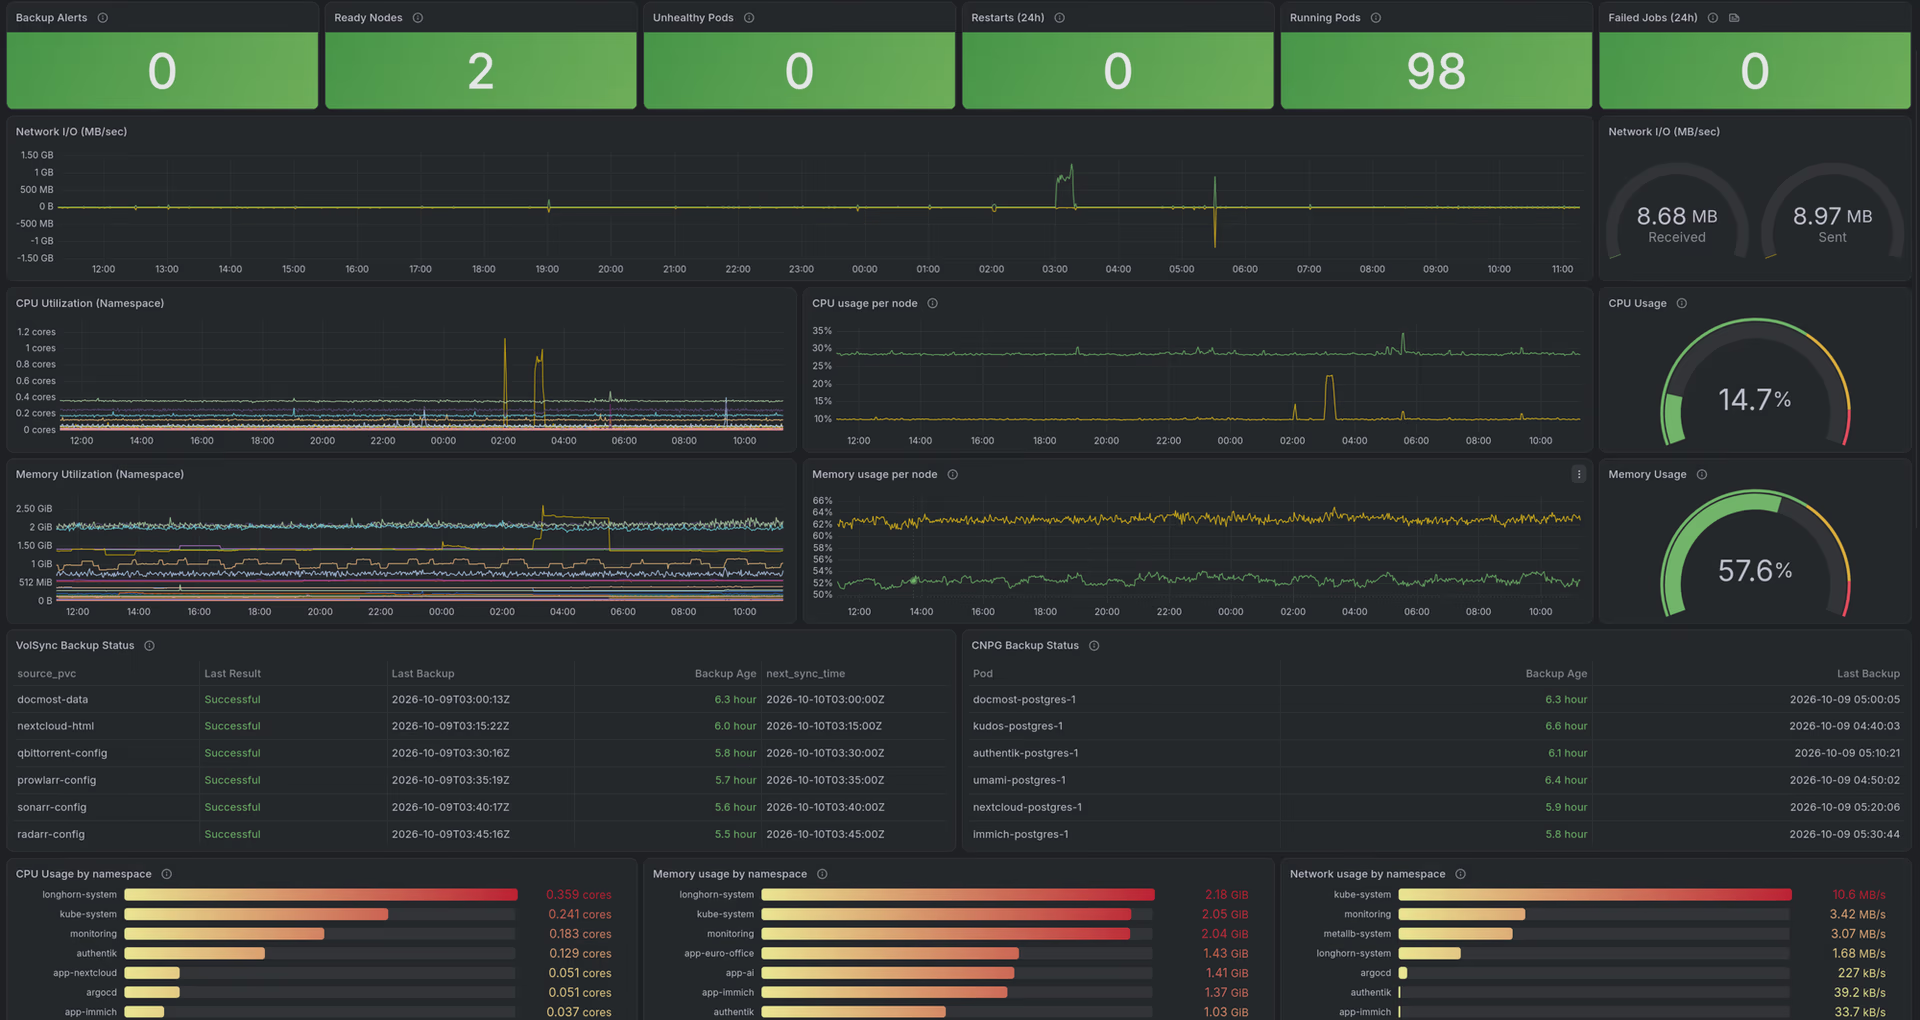
Grafana dashboard
Replying to @Legion739@piefed.zip
Ooooo, that looks nice.
Replying to @user224@lemmy.sdf.org
It’s running the private DNS for my phone. If it goes down, I realise quite quickly.
Replying to @user224@lemmy.sdf.org
My primary monitoring system is Beszel, but since I just migrated from VMs to LXCs it can’t properly see the memory/CPU usage, so it just checks for disk usage and liveliness. Home assistant with Proxmox & Dockhand integrations gives me the rest of my monitoring needs.
Replying to @dimjim@sh.itjust.works
I am also using Beszel after using checkmk. For me checkmk was way too complicated (but is also way more powerfull) to setup and maintain propperly. So I switcheed to beszel because it is much easier and good enough for my use case which is:
Besides that I don’t need anything. The only thing missing is SNMP support to check switches, routers and AP’s.
Replying to @dimjim@sh.itjust.works
I’ve been checking several other solutions before and Beszel just hits the spot.
Replying to @Alfredolin@lemmy.zip
If you run Proxmox and Proxmox Backup Server, I actually JUST found a better product for my needs, Pulse
My only problem with Beszel is that it doesn’t know about LXCs within Proxmox, so I can’t see if there are CPU/memory issues happening within them. Pulse integrates directly and can see all of it!
If you don’t run LXCs within Proxmox, I’d say stick with Beszel.
Replying to @user224@lemmy.sdf.org
Uptime Kuma for outages, Prometheus for metrics, rsyslog to Loki backend for logs. Grafana for ingesting Prometheus and Loki data.
Replying to @user224@lemmy.sdf.org
Acronyms, initialisms, abbreviations, contractions, and other phrases which expand to something larger, that I’ve seen in this thread:
Fewer Letters More Letters AP WiFi Access Point DNS Domain Name Service/System ISP Internet Service Provider LXC Linux Containers NAS Network-Attached Storage NFS Network File System, a Unix-based file-sharing protocol known for performance and efficiency RAID Redundant Array of Independent Disks for mass storage SSH Secure Shell for remote terminal access TLS Transport Layer Security, supersedes SSL ZFS Solaris/Linux filesystem focusing on data integrity[Thread #122 for this comm, first seen 9th Oct 2026, 13:00] [FAQ] [Full list] [Contact] [Source code]
 Hachyderm.ioImran Nazar ~ عمران نزر (@Two9A@hachyderm.io)3.05K Posts, 306 Following, 284 Followers · Front-end #typescript developer and general keyboard tapper; author of Internet RFC 7168 (Hypertext Coffeepot Control Protocol for teapots); occasional plumber, more than occasional #c64 #retrocomputing enthusiast, terrible at classical #piano.
Header photo is a verdant scene looking over the landscape near Buxton, England, taken from a single-track country road.
Replying to @user224@lemmy.sdf.org
You guys are monitoring your servers?
Replying to @bertlewirth@lemmy.world
“can’t access this thing, server must be down”
Replying to @InFerNo@lemmy.ml
I’ll fix it when I get home
Replying to @bertlewirth@lemmy.world
I plan to perhaps, just maybe, I am not sure, to try self-hosting an email server. But I’ll need a good uptime.
Although I am really scared about security.
Replying to @user224@lemmy.sdf.org
Well, it’s a good learning experience. But…… don’t. Good luck getting around the major email providers’ smart screen shit. It’s probably not gonna happen. I tried a few years ago, and even microslop couldn’t figure out why their shit screen crap wouldn’t allow my emails. It’s not in their best interest to fix it. So they don’t. But it’s worth doing it in the short term to learn how to do it. Teaches you about email, spf, dkim etc. which actually does translate to real world skills. I used what I learnt setting it up in my real life job.
Replying to @bertlewirth@lemmy.world
Yeah, email is one of the more annoying things to self host. Google rejects mine because my ISP has all their non static IPs on block lists (even though my IP hasn’t changed once since I’ve been with them it’s still not “static”, can’t change the reverse DNS) and I’m not paying 150% more a month for a business account to get a static IP. I ended up just using a free email relay. Still had to setup SPF, DKIM, DMARC, and all that jazz still.
Replying to @Dultas@lemmy.world
Yup. It’s so damn annoying hosting email. Do it once to learn, but don’t do it as a permanent solution. It takes so much maintenance to keep it going, if you even do get it working.
Replying to @bertlewirth@lemmy.world
What maintenance do you mean? run OS updates and pay the vps bill. that’s true for any self hosted application. which specific maintenance are you referring to?
Replying to @InFerNo@lemmy.ml
Setting up the newfangled security thing. TLS, DKIM, DMARC, SPF are the big ones over the years. Finding out you’ve been silently blackisted by a provider and hoping and praying they’ll answer your request to unblock. Managing your own spam filter.
Replying to @user224@lemmy.sdf.org
Been running one for many years, mostly issue-free. Had to request whitelists way in the beginning, but things turned out ok.
Check out this super great guide. workaround.org/ispmail-trixie
Replying to @user224@lemmy.sdf.org
I self-host my own email, have done so for years. I’ve not gotten pwned. Use an SSH key and a firewall, only expose the ports that should be public, have reasonable access controls, etc, just practise general cybersecurity—it applies to servers too.
I know everyone complains about hosting email. But I’ve not run into major problems. My emails get through spam filters and I have good uptime. It’s also a fun learning experience.
Replying to @communism@lemmy.ml
I think that you have to do quite a bit more setup on email than most other services. There’s SPF and DKIM and DMARC and so on. Plus spam filtering, setting up accounts and authentication, …
Plus email is arguably more important than anything else, since it’s kind of the lowest common denominator of the Internet; your dentist will probably send you an email to remind you of appointments, job offers will arrive via email, password resets arrive via email, and so on.
So it is a bit scary.
Having said that, as long as you’re not hosting from a residential IP addresses it is definitely achievable. You can start with one domain and use it for low-value purposes (or for accounts that allow multiple email addresses, like GitHub).
Replying to @NotEasyBeingGreen@slrpnk.net
Yes, it can be a bit involved. I’d say I can spin up a mail server in 1–2 days though provided the OS is already installed and I have a domain name and port 25 isn’t blocked (that’s the main one that tends to be blocked). It may take longer for people who aren’t familiar with mail servers but it’s not some huge operation.
You can just try spinning up a mail server for fun. If it goes badly then just don’t move over your dentist appointments to it. It’s only critical infra if you use it for critical things, which you probably shouldn’t till it’s stable.
Replying to @bertlewirth@lemmy.world
Seriously. I just kinda check it out once in a while.
Replying to @user224@lemmy.sdf.org
I notice something stopped working, or someone in the household notices.
Then I go fix it.

Replying to @CompactFlax@discuss.tchncs.de
And the best time to notice that the backups weren’t working is when you need access to the backup. 😅
Replying to @DeathByDenim@lemmy.world
Backups? In this economy?
But I need to get something working. I am about to move to VaultWarden and that makes me very nervous.
Replying to @CompactFlax@discuss.tchncs.de
I run a vaultwarden container since forever and it’s really smooth. All updates went through just fine, never had an issue with it.
Replying to @Carol2852@discuss.tchncs.de
Same. And I was also nervous in the beginning, but in the end if you are the only user, you’ll have your vault replicated everywhere you have the app.
Replying to @CompactFlax@discuss.tchncs.de
Don’t take this as a reason to not do backups, but vaultwarden is essentially its own back up as it replicates the vault everywhere you use the app. I’ve recovered my vault several times from my phone.
Replying to @Vendetta9076@sh.itjust.works
I’m just using Dropbox now and replicating my 1Password everywhere and for some reason it makes me nervous to self host.
I think I’m just going to back up everyone’s vault to a USB and bring it to a second location twice a year. If storage ever gets affordable, I’ll send replication snapshots instead.
Replying to @DeathByDenim@lemmy.world
Backups are pretty much the only thing I get notifications for. Otherwise, one app or another on my phone will complain if it loses connection to my server.
Replying to @electric_nan@lemmy.ml
That and degraded RAID!
Replying to @user224@lemmy.sdf.org
Netdata, looking at dashboards when something breaks :)
I go the easy route with munin and wazuh. It comes with a ton of stuff preconfigured
Replying to @user224@lemmy.sdf.org
Monit, simple to setup, gets the job done, runs on my router too.
Replying to @RIotingPacifist@lemmy.world
I have this on my NAS, works well
Replying to @user224@lemmy.sdf.org
I just look at the console.
Uptime Kuma for monitoring web service status (just like if the jellyfin, etc. website is up), and Zabbix for monitoring system metrics like CPU/Memory/Disk I/O, etc. Zabbix can do a whole lot, but can also get a little complicated. There are plenty of guides out there for configuring it though.
Replying to @user224@lemmy.sdf.org
My 3-node Proxmox cluster has a dashboard, my NAS has a dashboard, and Home Assistant has a dashboard. Hell, my gaming PC has a dashboard, too (Webmin and Cockpit).
Replying to @user224@lemmy.sdf.org
I am using prometheus-nodeexporter which is scraped by Prometheus and then visualized in Grafana
Replying to @user224@lemmy.sdf.org
Ultime Kuma, Beszel and Ntfy
Replying to @user224@lemmy.sdf.org
Icinga and Phare Uptime
Replying to @user224@lemmy.sdf.org
Use service, wait for 404 or data loss…
Replying to @user224@lemmy.sdf.org
Beszel & Pangolin.
Replying to @user224@lemmy.sdf.org
Gatus. Works and easy incremental set up.
Replying to @user224@lemmy.sdf.org
I use Signoz and OTel collectors to bring in everything from Kubernetes (and also SNMP-to-OTel for the network and NAS stats.)
That covers dashboards and basic alerting. Then on top of that I have an n8n workflow that runs every morning - it pulls all the main stats out of Signoz, as well as issues and their status from my infrastructure repo in Gitlab, and feeds it all into a local LLM (Qwen-3.8-Flash-Next at the moment), which emails me a report on overall cluster health. It also automatically opens a ticket in Gitlab for anything that might need fixing.
It works really nicely, gotta say.
Replying to @user224@lemmy.sdf.org
They’re in my attached garage. In the living room when it’s quiet I can hear them humming. Does that count?
Replying to @Joelk111@lemmy.world
“Oh the fans ramped up, something must be going down”
Replying to @user224@lemmy.sdf.org
Prometheus & Grafana
Replying to @user224@lemmy.sdf.org
I have a basic dashboard set up in my home assistant that I never check. Don’t even know how it works, I forgot. That’s why I really want to just put my whole setup in code. That’s why nothing is happening, the chore just seems so daunting.
So I listen for complains ringing through the house and react accordingly.
Replying to @user224@lemmy.sdf.org
I have the best detector for issues with my self hosted services: my wife!
Replying to @user224@lemmy.sdf.org
I run UptimeKuma for monitoring a couple of things, but honestly, I’m pretty much my only user and my homelab is independent of the regular home network, so I don’t really care too much. I’ve been considering some simple log monitoring… when I get around to it :-)
Beszel, uptime kuma, wazuh