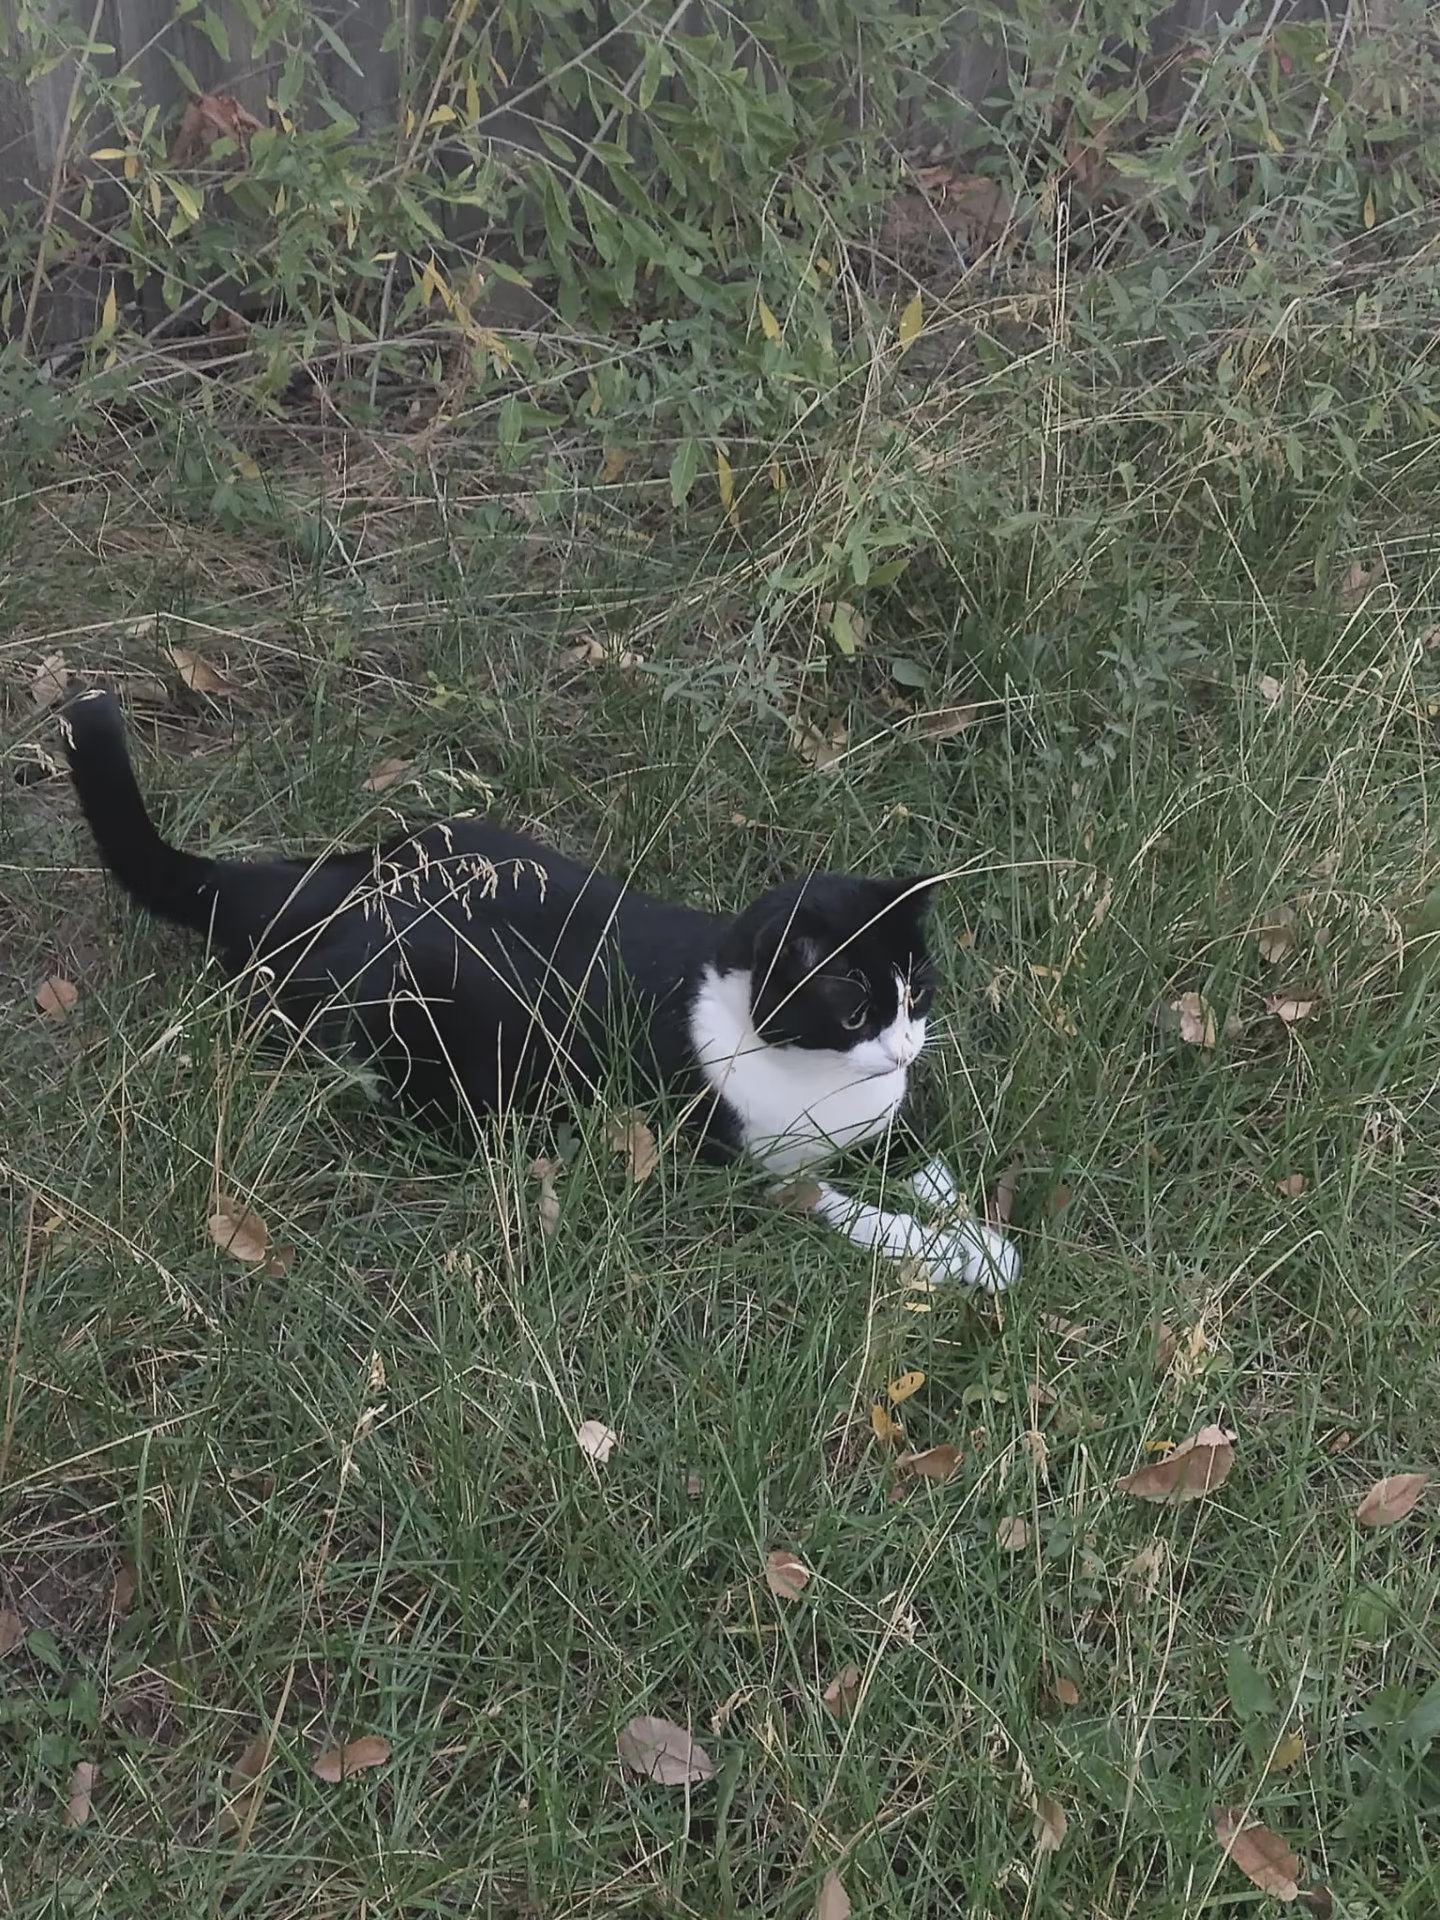
Please get your day off to a good start by enjoying this photo of Kiki getting some outside time
— Open image attachment 1 of 1
Research professor in the Kahlert School of Computing at the University of Utah. Co-director of the Flux Research Group: https://www.flux.utah.edu. I build research infrastructure: https://cloudlab.us, https://powderwireless.net, https://emulab.net .
I do not speak for my employer, nor do they speak for me
Certified Boffin ™
Zucchini user
Dragon Dad
Please get your day off to a good start by enjoying this photo of Kiki getting some outside time
— Open image attachment 1 of 1Replying to @lanodan@queer.hacktivis.me
@lanodan gotcha, wasn't familiar with them, thanks
Replying to @LinuxBSD@mivatter.com
@LinuxBSD Yes that's why I'm asking. There are accounts in here that I certainly wouldn't describe this way.
Was the list made based on links they posted to supposed scams? Boosts of posts that someone considers scams? Is there a particular definition of "scam" being used here? Did you make the list, or are you passing on something made by someone else?
I am interested in lists that help make the Fediverse a safer place, which is why I want to understand where this one came from - I want to understand where it came from and how it was created before I use it or recommend for anyone else to. My initial check suggests that it might not fit my needs, but I'd like to understand how accounts were actually added to it.
Replying to @LinuxBSD@mivatter.com
@LinuxBSD Do you know how this list was compiled? There are several people in here that I am quite confident don't match the description you gave, so I'm wondering how it was created.
Replying to @evan@cosocial.ca
@evan OMG I have this problem SO OFTEN trying to get measurement papers published in academic venues, we answer some interesting question and the reviews are basically "but why didn't you answer this OTHER question", and I just want to respond to say *this is an interesting question and I have answered it, if you want to answer this other question, how about you answer it*
Replying to @liaizon@wake.st
@liaizon @evan well... what I'm doing is using a list of servers that are currently up, and just getting nodeinfo for them, so I do have a list of *some* historical servers that are gone now, but I doubt it's anywhere near as good as Evan's data.
Someone who might have good data is @minoru who has been crawling the lists of federate servers for several years now to make https://nodes.fediverse.party/ (the list I use), and would have probably have a bunch of no-longer-reachable nodes in his database, including ones that were only known by nodes that are themselves no longer up, etc.
nodes.fediverse.party/Replying to @liaizon@wake.st
@liaizon Good idea! It's already in my data (https://arewedecentralizedyet.online/map/fedi-mau/fedi-mau-geo.json) so it'll be pretty easy to add. Will do when I get some time.
And argh, I swear I fixed the Carto API key thing, I must be installing from a checkout I didn't pull on
Replying to @liaizon@wake.st
@liaizon ohhhhhh
Replying to @liaizon@wake.st
@liaizon wait, what did I miss?
Replying to @ricci@discuss.systems
@SnoopJ @davidcelis @glyph brb renaming all my wifi SSIDs "give Rob monies"
Replying to @SnoopJ@hachyderm.io
@SnoopJ @davidcelis @glyph this is probably how they got the money
Replying to @liaizon@wake.st
[For context, this is about #atproto / #bluesky]
Couple things:
1) Yes, it is generally the case that AppViews are, by far, the more expensive thing to run now; there is some stale information about relays being expensive because they used to hold full network history. However, this has changed and not even the Bluesky-run relays do this anymore. The cost of running the relay is just the bandwidth, which is currently around 20Mbps - negligible storage, fairly low compute needs, not a ton of RAM.
2) The AppView is now the main part of the network that has to store a bunch of stuff, have the necessary compute to be doing constant stores and lookups, and lots of RAM to hold caches and indexes, etc.
3) As pointed out above, this is for *Bluesky* records, you can put, to a first approximation, whatever data you want on the network, and if you are building an app that doesn't need to see every Bluesky post, like a long-form publishing app, your AppView can be much smaller.
HOWEVER
4) Costs are in large part proportional to the *number of subscribers pulling data from them*. Yes, if you run a relay and no one uses it, it's cheap; 20Mbps in is not expensive these days (in fact, I am bringing *five* complete copies of the network into my living room from different relays for Reasons). BUT if you are going to run a relay that has very many subscribers, this changes. I highly doubt that any of the indie relays running now (of which there are several) could take over the load of the Bluesky-run relays.
5) All of the above is true of the *current* network. If you believe the people that claim that atproto is not just about micoblogging, and is the foundation of the future Internet, then 20Mbps is laughably small, and almost certainly means that a relay - with the current architecture - would be out of basically everyone's reach in the future.
6) The data model in atproto means that if you want to see things that reference your records (replies, likes, mentions, etc.) then *someone* has to see and index them. At the current network size, this is not too bad, and people run services to do this, that get real usage, on Raspberry Pis. But, this only stays true if the network stays fairly small, see point above.
7) Bluesky is making a network node called Jetstream, which is a different sort of relay, more capable and it will probably become even more central than it already is; the new version of Jetstream DOES have history data, and it's operations are more complex (does more cryptography and data validation, can serve subsets of the network to subscribers). So, it may very well shift back to being the case that the *kinds of relays that matter* are expensive to run. In large part this is because:
8) The basic data and network models stream *everything*, not just the kinds of records your app uses. You are running a longform blog app and need to see when your 1,000 users publish new entries? Congratulations, you have to listen to everything that happens on any app on the network from all users everywhere. Doable in the current network, but obviously absurd if you believe the "protocol of the future network" story. This is the problem that Jetstream solves: it lets you subscribe to just the bits of the network you want. Great. But, it means that relays are fundamentally more expensive to run since instead of basic pipes that just do fan-out, they have to do subsetting and feed different stuff to each subscriber. So, if the network, and the number of apps it grow, there is a shift back from cheap relays to potentially very expensive jetstreams.
@mo sure! we'd want to be a bit careful about not blindly pulling all lists since that could make the whole thing take a long time if someone has a lot of them (and not necessarily helpful if they don't have them exclude as you do) but I'm sure we can figure something reasonable out
@mo I think that would be fairly complicated, I think I'd have to crawl the home timeline, all list timelines, and deduplicate stuff that appears in more than one :)
@mo It hits the `timelines/home` API, which I *think* is the same one used for home timeline in the web interface and most other clients. So I *think* it's excluding your lists.
I should probably add a very simple timeline view to make this easier to tell
What would happen to your timeline if mastodon.social went away?
(Reposting my tool that helps you figure this out.)
mastodon.social is the biggest server on the #fediverse , with over 21% of accounts, and an even higher percentage of #Mastodon accounts.
But what does that mean to you, personally? Let's say it went away tomorrow - (assuming you aren't on it yourself), how much of your timeline would vanish?
In my case, it turns out - not a lot, actually! The biggest sources of posts that I see are (1) a very small instance that doesn't even federate with much of the Fediverse, but many of my friends are there, (2) my own instance, (3) a large tech-focused instance that is still much smaller than mastodon.social. The big guy is only 5% of the post I've seen recently.
But this might be different for you!
Find out for yourself at https://moderation-explorer.online/ . Use 'advanced mode' to see this analysis, since you need to log into see your actual feed.
You might even decide to try moving to an instance that you're more connected to?
(It's explained more on the site, but all the work happens in your browser, I don't see your identity, auth tokens, posts that get loaded, none of it.)
Replying to @stefan@stefanbohacek.online
@stefan haha, wow, my first website would be like 29 years old, crazy how much closer it is to the existence of the first one than today!
Yes, IA has it. No, I will never give you the link.
Replying to @lina@neuromatch.social
@lina time to liquidize your goose and buy some gold